Showing posts with label autostats update. Show all posts

Monday, February 28, 2022

#SQLServer Trivial Plans for Inserts; Stats Expectations and Reality

OK.  SQL Server trivial plans for rowstore table INSERT. And related optimizer stats interaction.

TL;DR cached trivial plans for INSERT can be surprisingly stubborn. If a query matches to one, it won't perform or queue a stats update even if the stats are stale.  If the stats have been updated and would otherwise warrant a per-index plan - but there is a matching cached trivial plan for a per-row plan... outta luck. Might hafta DBCC FREEPROCCACHE or add OPTION(RECOMPILE) hint to make sure a cached trivial plan doesn't prevent a per-index update for an INSERT when you really want one.

~~~~ 

The blog post referenced below, first published 2015 March 16, is pretty good.

The relevant takeaway from that post is: in a database with AUTO_UPDATE_STATISTICS = ON, a statistics update will NOT invalidate a relevant cached query plan. A subsequent query which qualifies to use a cached plan will continue to use the cached trivial plan. This is Scenario 1 in the blog post. The following text is directly from the blog post.

When a plan is trivial, it’s unnecessary to recompile the query even statistics has been updated.  Optimizer generates trivial plan for very simple queries (usually referencing a single table).  In XML plan, you will see statementOptmLevel="TRIVIAL". In such case, it’s futile and you won't get a better or different plan.

The demo code in the blog post uses SELECT queries only. In my examples in my own blog post, I'm concerned with INSERT queries.  Are INSERT queries eligible for both trivial plans and plans that have been more fully optimized? If INSERT queries can use a trivial plan, is it possible for a cached trivial plan to remain in use when a better and/or different plan could be selected?

Perhaps the reader is familiar with the Paul White blog post referenced below, from 2013 January 26. In that blog post, Paul White discusses wide, per-index INSERT query plans and narrow, per-row INSERT query plans.  How do these plan types relate to trivial plans?

OK. Enough jibber-jabber. Time to do something. Like create a stored procedure.  Which will be used in a database with AUTO_UPDATE_STATISTICS = ON and AUTO_UPDATE_STATISTICS_ASYNC = OFF.

This stored procedure will drop two tables if they already exist, then create those two tables.  The source table has three columns and a single index - the clustered primary key.  The target table also has three columns and a clustered primary key. In addition the target table has two non-clustered indexes.

The @insert_no_rows parameter controls whether or not there will be an INSERT query from the empty source table to the empty target table. That wouldn't move any data - but maybe it will cache a plan?

The INSERT query is dynamic SQL - both in the stored procedure and when I issue it adhoc later.  It isn't necessary for this query to be dynamic SQL - it was just easier that way to make sure the batch SQL text matched and plan re-use happened when it was a possibility. While writing this blog post at one point the query SQL text in the stored procedure has a different number of tabs preceding the formatted T-SQL than appeared in my adhoc query afterward and it took me forever to figure out why plan re-use wasn't occurring. :-) 

CREATE OR ALTER PROCEDURE test__trivial_plan_inserts @insert_no_rows INT = 0, @x INT = 0
AS
BEGIN
	DROP TABLE IF EXISTS trivial_test_source;
	DROP TABLE IF EXISTS trivial_test_target;

	CREATE TABLE trivial_test_source
	(	col1 INT CONSTRAINT pk__trivial_test_source PRIMARY KEY CLUSTERED
	,	col2 INT
	,	col3 INT
	);

	CREATE TABLE trivial_test_target
	(	col1 INT CONSTRAINT pk__trivial_test_target PRIMARY KEY CLUSTERED
	,	col2 INT INDEX nci__trivial_test_target__col2
	,	col3 INT INDEX nci__trivial_test_target__col3
	);

	-- white space in the INSERT dynamic SQL must match exactly
	-- in stored procedure and adhoc EXEC for cached plan reuse
	IF @insert_no_rows = 1
	BEGIN
		DECLARE @sqlT NVARCHAR(1000) = N'INSERT INTO trivial_test_target SELECT * FROM trivial_test_source;'
		EXEC (@sqlT);
	END
	-- white space in the INSERT dynamic SQL must match exactly
	-- in stored procedure and adhoc EXEC for cached plan reuse

	;WITH	n0 AS (	SELECT TOP (32) n = 1 
					FROM master.dbo.spt_values)
	,		n1 AS (	SELECT n = ROW_NUMBER() OVER (ORDER BY(SELECT NULL))
					FROM n0 t1 CROSS JOIN n0 t2)
	INSERT INTO	trivial_test_source
	SELECT		TOP (@x) n, n, n
	FROM		n1;
END

For the first experiment, let's not worry about caching plans. Let's call the stored procedure like this:

EXEC test__trivial_plan_inserts @insert_no_rows = 0, @x = 1023;

So, give me 1023 rows in table trivial_test_source.

After the stored procedure executes, let's grab an actual plan from this simple INSERT query:

DECLARE @sqlT NVARCHAR(100) = N'INSERT INTO trivial_test_target SELECT * FROM trivial_test_source;'
EXEC (@sqlT);
-- white space in the INSERT dynamic SQL must match exactly
-- in stored procedure and adhoc EXEC for cached plan reuse

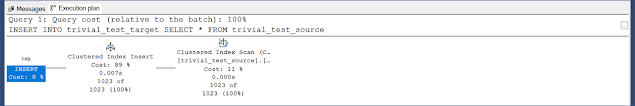
And here's the actual plan.  That's a narrow, per-row plan. Note the estimate of 1023 rows; dead-on.


The Object properties in the graphical plan specify the target table indexes which will be updated for each row inserted into the clustered index. So far, so good.


If we look at the plan XML, we can see this is a trivial plan.


OK. Now let's call the stored procedure like this:
EXEC test__trivial_plan_inserts @insert_no_rows = 0, @x = 1024;


That will drop the source and target tables, recreate the tables, and populate the source table with 1024 rows instead of the previous 1023.

Now get an actual plan for the insert again:

DECLARE @sqlT NVARCHAR(100) = N'INSERT INTO trivial_test_target SELECT * FROM trivial_test_source;'
EXEC (@sqlT);
-- white space in the INSERT dynamic SQL must match exactly
-- in stored procedure and adhoc EXEC for cached plan reuse

And... bam!!! Yeah, the graphical plan below certainly looks like a different plan. This is what Paul White refers to as a wide, per-index update.

First, at the right of the blue box below, the source table scan operator feeds rows into the clustered index insert operator. No sort is needed to optimize the insert because the source and target tables have the same primary key clustered index definition. These rows are also fed into a table spool at the left of the blue box below.  The table spool at the left of the blue box is the same table spool at the left of the gold box - just different zones of the same plan.


Table spool populated, it is used as a source for a sort, then insert into a non-clustered index.  This happens once in the upper blue box, then again in the lower gold box.


Demonstrating the benefit of a per-index update over a per-row update for an INSERT of many thousand rows is left as an exercise for the reader.

While I won't investigate at this time, I do want to make note of an interesting switcheroo that takes place. Recall that within the CREATE TABLE, the clustered primary key and the two non-clustered indexes on col2 and col3 were created with inline syntax.


How did the non-clustered index on col3 become index_id 2, while the nonclustered index on col2 became index_id 3?  I don't know - and i don't know of anywhere that could be consequential. Yet.


How did I notice that little switcheroo?  Well, every per-index INSERT graphical plan I've seen has shown indexes in index_id order from top-down.  And when I've observed large per-index updates with sys.dm_tran_locks, the acquisition of locks over time by the session indicates indexes are tended to in index_id order.  I won't at this time be investigating further whether per-index updates always handle indexes in index_id order, or how the little index_id switcheroo occurred. Just an interesting bread crumb.

Before we do the next part I want to make sure the database is set up like I think...
Excellent, exactly what I wanted.


So. This time we drop the tables and recreate them. We issue the INSERT INTO... SELECT while both source and target tables are empty. Then populate the source table with 1024 rows.

EXEC test__trivial_plan_inserts @insert_no_rows = 1, @x = 1024;

And now we are ready to grab an actual plan...

DECLARE @sqlT NVARCHAR(100) = N'INSERT INTO trivial_test_target SELECT * FROM trivial_test_source;'
EXEC (@sqlT);
-- white space in the INSERT dynamic SQL must match exactly
-- in stored procedure and adhoc EXEC for cached plan reuse

So now we have 1024 rows - that number of rows previously got a per-index update plan.  But this time it got a per-row plan. Huh.


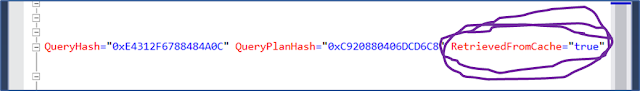
Well, what the heck.  If we look at the plan XML we see a clue. RetrievedFromCache.


Now wait just a minute. That source table went from 0 rows to 1024 rows; did the stats get updated?

Wow. I guess not. When the insert matched a cached trivial plan, the stats did not get updated even though they were stale and auto update stats is true in this database.


So - what if I try this again? Drop the tables, recreate the tables, run the insert with zero rows to put a plan in the cache. Put 1024 rows in the source table. Then... I'll explicitly update stats.

EXEC test__trivial_plan_inserts @insert_no_rows = 1, @x = 1024;
UPDATE STATISTICS trivial_test_source;

OK, stats are updated.


So what happens now? Ouch. It doesn't matter.  If the stats are stale and there's a matching cached trivial plan - the stats don't get updated.  If the stale stats ARE updated before the query is executed - the matching trivial plan isn't invalidated. So that matching cached trivial plan will still be used. Even though I don't want it to be used. I just want SQL Server to take a fresh look at what's going on.

And that fresh look can solve the problem.  Clearing the plan cache with DBCC FREEPROCCACHE (or ALTER DATABASE SCOPED CONFIGURATION CLEAR PROCEDURE CACHE in the relevant database) would cause SQL Server to take a fresh look, and decide if the INSERT should get a per-index plan instead of a per-row plan*.  Tacking OPTION(RECOMPILE) hint on to the end of that INSERT would also work in a much more targeted manner. Sometimes, in order to prevent a cached trivial plan from forcing a per-row update when we really want a per-index update, gonna hafta encourage SQL Server to take a fresh look in one of those ways.

*There are a number of SQL Server instance-wide configuration settings changes to which will also clear plan cache, such as maxdop and cost threshold for parallelism. But i don't recommend changing any of them solely to clear plan cache. Microsoft lists the configuration options which clear plan cache on the following BOL page.

Sunday, February 17, 2019

SQL Server 2016 SP2 CU4/2017 CU13 Access Violation on Certain Autostats Updates

***** Updated 2019-02-18 This post was originally published on February 17th, 2019. February 18 it was updated with some details re: SQL Server 2016 SP2 CU3 and CU5 - the CUs immediately preceding and following the CU4 with the av. The repro has been updated from repro version 58 to repro version 62. This version does a better job of giving results which can easily be compared across CU3, CU4, and CU5. *****


I spent a lot of time tracking this error down.

When I started investigating, the error was known only as an access violation, preventing some operations related to data cleansing or fact table versioning.

It occurred deep within a series of stored procedures.  The execution environment included cross-database DELETE statements, cross-database synonyms, lots of SELECT statements against system views, scalar UDFs, and lots and lots of dynamic SQL.

And... I don't have access to the four systems where the access violation occurred.

I was able to have some investigation performed on those systems - we learned that by disabling 'auto stats update' for the duration of the sensitive operations, the error was avoided.  We also learned that reverting a system from SQL Server 2016 SP2 CU4 to SP2 CU2 avoided the errors.  On those systems, reverting to SP2 CU2 or temporarily disabling 'auto stats update' were sufficient temporary mitigations.

So I set out to reproduce the errors on my laptop.  That took a while.  A pretty long while. 😱

And once I was able to reproduce the access violation, I generated 16 errors and suddenly couldn't get anymore errors!  (I'd later learn that changing the database recovery model from 'simple' to 'full' was the reason the errors were no longer occurring.)  I opened a premier support ticket with Microsoft describing the issue and attaching the sqldump files, and explaining I wasn't able to continue generating the errors.

Fortunately it was only a few hours later that I was able to start generating errors again by proceeding through my process of reproducing errors and simplifying the context much more carefully than previously.

At the bottom of this post is a minimal reproduction of the access violation error in SQL Server 2016 SP2 CU4.  As is, the statements will create a new database t1 with simple recovery mode and 'auto stats update' enabled.  Those are the system state requirements for the access violations.  If you recreate the error yourself, please be aware a memory dump will be created.

The execution context required for the access violation requires a stats object that is already created but empty.  So a stats object for a clustered index(or primary key clustered index) on a table that was just created, or has been truncated.  The underlying column must be BIGINT data type.  With INT, the error does not occur (or at least doesn't occur until a much higher threshold of activity).

Within the same explicit transaction, at least 1024 rows are inserted into the table using the TABLOCK or TABLOCKX hint (without a hint no error will occur), and then a query requests the stats (resulting in the auto-update stats activity).  Then the access violation occurs.

If you'd like to follow along, here is the repro code.

DECLARE @version NVARCHAR(50) = N'SQL Server ' + CONVERT(NVARCHAR(20), SERVERPROPERTY('ProductVersion')) 
SELECT [version] = @version 
PRINT @version
USE [master]
GO
DECLARE @dpath NVARCHAR(200), @lpath NVARCHAR(200), @dbcmd NVARCHAR(1000);
SELECT @dpath = CONVERT(NVARCHAR(100), SERVERPROPERTY('InstanceDefaultDataPath')) + N't1.mdf';
SELECT @lpath = CONVERT(NVARCHAR(100), SERVERPROPERTY('InstanceDefaultLogPath')) + N't1_log.ldf';

SET @dbcmd = N'CREATE DATABASE [t1] ON PRIMARY (NAME = ''t1'', FILENAME = N''' + @dpath + N''', SIZE = 8192KB , MAXSIZE = 1GB, FILEGROWTH = 65536KB )'
SET @dbcmd = @dbcmd + N' LOG ON ( NAME = N''t1_log'', FILENAME = N''' + @lpath + N''', SIZE = 8192KB , MAXSIZE = 1GB , FILEGROWTH = 65536KB );'
SET @dbcmd = @dbcmd + N' ALTER DATABASE [t1] SET RECOVERY SIMPLE,  AUTO_UPDATE_STATISTICS ON,      AUTO_UPDATE_STATISTICS_ASYNC OFF;'
/*                                           RECOVERY SIMPLE ONLY, AUTO_UPDATE_STATISTICS ON ONLY, AUTO_UPDATE_STATISTICS_ASYNC ON or OFF   */
EXEC (@dbcmd)
GO
USE t1
GO
SELECT repro_id = 'x62';
PRINT 'repro_id = x62'
/* both DROP and CREATE TABLE can be replaced with
   IF OBJECT_ID('x') IS NOT NULL TRUNCATE TABLE x 
   access violation takes place for empty stat either way */

DROP TABLE IF EXISTS x
CREATE TABLE x  ( col1 BIGINT -- No error if INT rather than BIGINT
                  INDEX ci_x CLUSTERED (col1) -- stats on CI or PKCI for access violation on auto stats update
--                index i_col1(col1)) -- nope, no av if stats accompany non-clustered index
                )
--CREATE STATISTICS s_col1 ON x(col1); -- nope, no error if stats on non-indexed column
                                       -- only auto stats update of stats on CI or PKCI seems to hit AV
                  
GO
--Transaction can include or exclude CREATE TABLE but must include INSERT and request for auto stats update
BEGIN TRANSACTION

  ;WITH u0 AS (SELECT num=1 UNION ALL SELECT num=1),             -- 2 rows
        u1 AS (SELECT num=1 FROM u0 AS n1 cross apply u0 AS n2), -- 2 * 2 = 4 rows
        u2 AS (SELECT num=1 FROM u1 AS n1 cross apply u1 AS n2), -- 4 * 4 = 16 rows
        u3 AS (SELECT num=1 FROM u2 AS n1 cross apply u2 AS n2), -- 16 * 16 = 256 rows
        u4 AS (SELECT num=1 FROM u3 AS n1 cross apply u1 AS n2), -- 256 * 4 = 1024 rows
        nums AS (SELECT num=ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) FROM u4)
  INSERT INTO x WITH ( TABLOCKX ) -- TABLOCK or TABLOCKX to get av; no hint no error
  SELECT TOP (1024) num -- no av if less than 1024 rows
  FROM nums;

  --SELECT result = COUNT (DISTINCT col1) FROM x -- stats auto update in CU3, CU4 or CU5; but no av
  SELECT result = COUNT ( * ) FROM x -- stats auto update in 2016 SP2 CU4 but not CU3 or CU5 
  /* access violation takes place when auto update stats is attempted in 2016 SP2 CU4 */

  COMMIT TRAN
  DBCC SHOW_STATISTICS (x, ci_x) WITH STAT_HEADER, NO_INFOMSGS;
GO
/*
USE [master]
DROP DATABASE [t1]
*/


Here's what the output of the repro code below looks like on SQL Server 2016 SP2 CU3.  Not terribly exciting.  Note that at the end of execution, the stats for ci_x are still empty.  That makes sense - a count(*) from a table can't really benefit from stats.  It doesn''t have an operator accumulating results over time or anything else requiring a memory grant.  Doesn't have a join operator requiring a row estimate.


Indeed, the results look identical in SQL Server 2016 SP2 CU5.  No auto stats update, no error, stats still empty as the code completes.


But what happens in SQL Server 2016 SP2 CU4?  Just after the rows are inserted - and before the results of the count(*) are returned - the query encounters an access violation.


The exception.log file in the SQL Server error log directory looks nice and orderly from these access violations :-)


And  here's the short stack dump included in the SQLDump****.txt files.


It really looks like SQL Server 2016 SP2 CU4 is a loner in this regard - asking for an auto stats update in a context where the stats are immaterial to the query itself.

We'll see.  If there is a fix forthcoming in SQL Server 2016 SP2 CU6 or beyond, I'll update this post with a reference to it.  Perhaps instead I'll learn that this issue was coincidentally fixed in SQL Server 2016 SP2 CU5.  I've looked through the CU5 kbar a few times and didn't see anything I thought was related.

I tried to document within the repro code potential 'bandaid' workarounds if you run into this access violation - just something to tide you over till can upgrade to a fixed version.  For example, switching to full recovery model or disabling auto stats update.  Unfortunately, innocculating against these AVs at the system level may come at too great of a risk in some cases.  There are workarounds possible in the code as well.  Eliminating hints in the insert might work without unreasonable cost.  Alternatively a manual stats update before the count(*) may be acceptable.

All right - that's it for now! Ciao!! 


***** Addendum 20190220 *****
I decided to check SQL Server 2017 as well.  CU11 - no error.  CU12 - no error.
CU13...


So be on the lookout for this access violation in SQL Server 2016 SP2 CU5 and SQL Server 2017 CU13.